
- legacy modernization
- strangler pattern
- platform architecture
- migration
Modernize a Legacy iGaming Platform Without a Full Rewrite
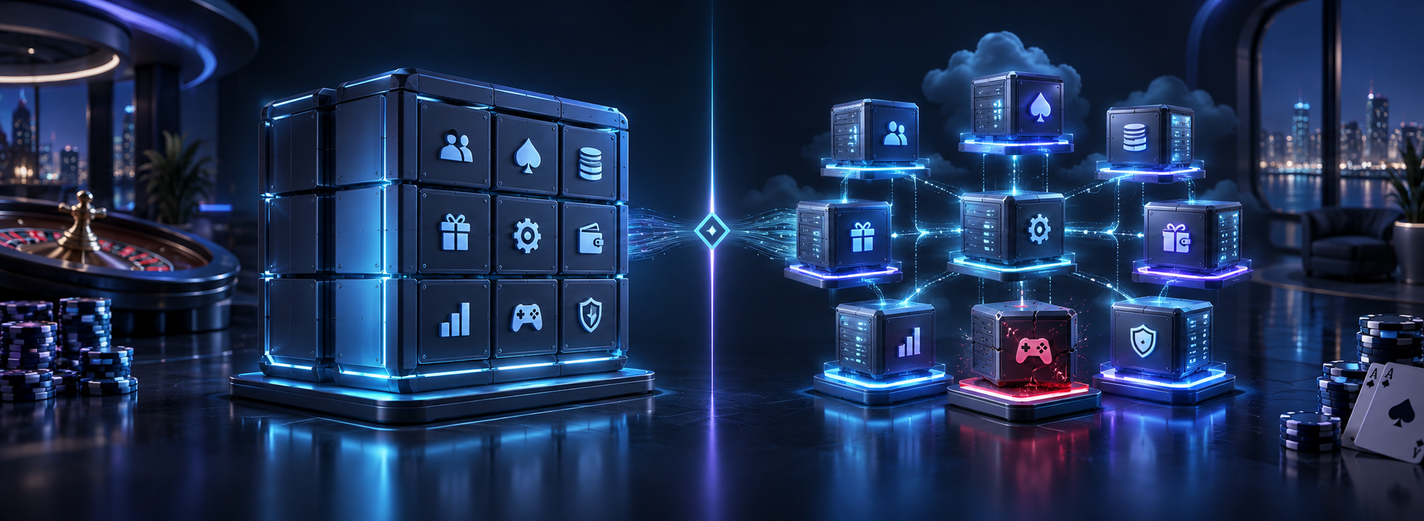
Choose a first modernization slice from real operating pain. Recover hidden rules, define replacement boundaries and retire old paths without creating competing financial authority.
A payout investigation takes too long because its history is scattered across screens and tables. A small promotion change requires a platform-wide release. A provider upgrade keeps slipping because nobody knows which jobs write directly to its records. These are useful reasons to modernize: they identify a business constraint that can be tested after a change.
An old framework alone does not tell you whether to replace a system. For an operating iGaming platform, the difficult part is often the behavior accumulated around money, player restrictions, integrations and staff workarounds. A new codebase can reproduce those problems, omit an obligation or introduce a second authority for the same transaction. This guide is for engineering and product leaders deciding where to start, what evidence to collect and how to stop a transition from becoming permanent.
Start with the operating constraint you need to remove
Write the problem in operational terms. Name the affected journey, the people doing the work, the delay or failure they experience, and the evidence that shows its cause. Distinguish a slow query from a missing transaction reference, and a cumbersome release process from an unclear product rule. They need different interventions.
Record a baseline under comparable conditions: elapsed time to resolve a payout case, steps requiring privileged access, change lead time for one product rule, or failures linked to a specific dependency. Keep the sample period, workload and definition of completion. A faster endpoint is a weak result if support still cannot close the same case.
Martin Fowler’s Strangler Fig account describes gradual replacement and stresses clarity about desired outcomes. Use that principle to state what the first change should make possible, rather than promising a completely new platform as the only meaningful result.
Set the constraints alongside the outcome: approved player-protection rules, financial records to preserve, provider arrangements, delivery capacity and staff coverage. The operator and qualified advisers supply applicable market requirements; the team must identify which changes need additional review. For a wider assessment, connect platform modernization with architecture decisions that can be implemented and checked.
Recover behavior before deciding what to preserve
Read the system as it operates, including scheduled jobs, database writes, provider callbacks, exports and staff tools. A diagram of the web application can miss a nightly script that changes the same state. Interview the people who resolve exceptions, then check their account against records and executable paths. Use authorized access and suitably protected or sanitized examples.
Create characterization tests: tests that capture observed behavior at a chosen boundary so a change can reveal a difference. Their purpose is to make behavior visible, not declare every historical rule correct. Label each example as behavior to preserve, a defect whose correction has been approved, or an unresolved policy question. Give the latter two a decision owner; otherwise the new implementation quietly makes policy.
For a payout-status improvement, assemble representative cases: accepted but unfinished, rejected before acceptance, accepted with a lost reply, a late success notification, a repeated notification, and a case already handled manually. Trace operation identifiers, reservation state, provider references and staff actions. Check what the player and support agent see at each point. Do not let a screen saying “failed” settle the question of whether the provider accepted the instruction.
The output is a small behavior pack: inputs, preconditions, observed records and effects, the intended result, and a reason for any deliberate difference. Include authorization and restriction checks. It can expose a safer first step: improve a read-only investigation view while leaving financial commands with their existing owner.
Compare impact, risk and dependencies before choosing a slice
Compare candidate changes with short decision records. A numerical ranking can conceal a blocking dependency or turn uncertainty into apparent precision. Use the following fields as a discussion aid; the decision still needs accountable judgement:
- Impact: whose problem changes, what outcome should improve, and the baseline used to recognize improvement.
- Risk: money, access or player obligations that could be affected; the reachable failure modes and the controls needed before release.
- Dependencies: code and data access, provider permission, shared writers, downstream reports and the people needed to resolve them.
- Evidence and exit: the smallest experiment that tests the assumption, the release criteria, and the old path or manual work that can actually be removed.
Consider three illustrative candidates. A read-only payout-history view can reduce investigation work while keeping existing write authority, but must enforce access and expose data freshness. Replacing a promotion evaluator can reduce release coupling, but first needs explicit eligibility and award semantics, including already active promotions. Replacing the wallet may remove a deep constraint, but is a poor starter experiment when all its writers and unfinished operations are still unknown.
Choose a candidate that delivers useful evidence and a controllable outcome within the team’s capacity. A prerequisite that prevents safe operation is a gate, not a low score to average away. If the highest-value candidate is blocked, commission the work that resolves that uncertainty or select another coherent slice. Record why the decision can be revisited; do not turn an exploratory order into a permanent architecture plan.
Create a replacement seam the team can actually control
A replacement seam is the place where callers can be directed to an old or new implementation through a controlled contract. The boundary might sit inside the application or at an external interface. It must cover the actual callers: APIs, jobs, provider callbacks and staff tools. A new endpoint alone does not intercept a direct database write.
Fowler’s Branch by Abstraction describes using an abstraction to let old and new implementations coexist during change. This can suit a library or rule evaluator inside one deployment. It does not require a new service for every replacement.
For an external routing boundary, AWS’s strangler guidance warns that a proxy can become a bottleneck or failure point. Its example targets microservices; the platform’s destination should still follow the actual ownership, consistency and operating needs.
Write the contract in terms of business meaning: identifiers, permitted commands, preconditions, results, uncertainty, retries and authorization. Translate legacy representations at the boundary without inventing a final result when information is missing. An adapter that converts every unknown payout status into rejection changes financial behavior even if its response schema is correct.
Choose the simplest deployment shape that makes the boundary useful. An internal module may reduce change coupling enough, even though deployment remains shared; a separate service adds network failures, independent deployment and additional operations. Compare modular monoliths and microservices against the intended benefit before choosing the distribution cost.
Keep data authority and unfinished work explicit
For each phase, name the authoritative writer and the readers for every affected state. A new read model can be derived from existing records while the legacy component remains the command owner. Make freshness visible where it matters, and keep decisions that require current authority out of a lagging view. A reporting copy is not a second wallet.
Moving write authority requires a separate plan. Inventory all writers, define a boundary at which existing changes have been accounted for, and prevent old and new code from issuing the same business command. Match records at a common checkpoint; equal row counts or aggregate balances alone cannot prove that individual reservations and operations survived. The detailed work belongs in live-platform data migration planning.
Do not confuse two independent database writes with a database update plus a notification. For the latter, AWS’s transactional outbox guidance records the change and its event in one transaction, with later delivery. Consumers still need duplicate handling; this does not make an external payout atomic with the platform database.
An illustrative transition: the old payout component has a pending operation already accepted by its provider. After routing changes, a late callback arrives. Choose and implement who owns completion of that particular operation: keep it with the old owner, or perform an explicit state-and-authority transfer that the new owner can recover. Preserve its identity, provider reference and financial effect. New routing must not authorize a second payout or leave neither owner able to finish it.
If the new writer has accepted work, reverting the route is not enough. The old implementation may lack the new records or understand them differently. Define recovery for that state, including whether to finish work with the new owner, synchronize supported state back, or stop new commands while resolving exceptions. Any transfer back needs tested compatibility and exclusive authority; stopping new commands does not cancel accepted obligations. Rehearse the chosen route before granting authority.
Release the replacement and pay down the transition
Separate evidence stages. First compare results using controlled fixtures. Then, where permitted, compare a read-only or side-effect-disabled shadow result against the authoritative path. Finally release the replacement to a bounded live scope with explicit ownership and stop conditions. These are different activities, not interchangeable meanings of “parallel run”.
A shadow payout command must not call the live provider, reserve money, send player messages or alter restrictions. Consider effects reached indirectly through jobs and events. Control data access, retention and workload so the experiment does not overload the existing platform or expose player information. Differences need classification: intended policy change, stale inputs, legacy defect, or replacement defect.
For the payout-history pilot, compare the same operation references and checkpoint, test access restrictions, and show how delayed data is marked. Measure whether authorized staff can resolve representative cases with fewer handoffs, alongside source load and unresolved discrepancies. For a writer replacement, add ownership, duplicate, late-callback and post-switch recovery tests. Set acceptance and stop criteria for the chosen scope; there is no useful universal traffic percentage or mismatch allowance.
Budget the transition explicitly: adapters, two supported implementations, data synchronization, observability, staff training and incident coverage. Each temporary component needs an owner and an exit condition. Before removing the old path, verify that callers, scheduled work, callback routes and historical access no longer depend on it. Preserve records under the agreed retention and access requirements; retiring executable code does not authorize deleting financial history.
Record the outcome against the baseline and the remaining transition cost. If releases still require coordinated changes everywhere, investigate the surviving dependency instead of claiming success from the number of new services. If an adapter has no credible removal path, decide openly whether it is now a permanent supported interface.
Know when incremental replacement is the wrong bargain
Incremental replacement is attractive when the business must keep operating, the system has useful behavior worth preserving and a controllable boundary can deliver value. It becomes less attractive when the component is small and well understood, coexistence costs dominate, or the required interception and operating access cannot be obtained.
A bounded rewrite can be reasonable if its obligations and callers are known, the interruption or transfer is approved, and migration and recovery can be demonstrated. Conversely, an unsupported runtime or a critical security issue may need an urgent containment or upgrade before any longer modernization plan. An attractive roadmap is not a substitute for resolving the immediate exposure.
The first proposal should therefore state the outcome, the evidence missing, the proposed boundary and the conditions that would change the approach. Fund a decision and a useful increment, then review what the platform actually made easier. The aim is a business that can change with control, including the capacity to remove old work when it is no longer needed.
Continue with the strangler migration roadmap for staged replacement and provider evaluation before integration when access, contracts or support determine the boundary. Use them to deepen the relevant decision rather than expand the first slice by default.
- Choose an operating problem with a comparable baseline and a named decision owner.
- Capture observed behavior, approved changes and unresolved policy questions before replacing the path.
- Define callers, authority, unfinished operations and recovery for every transition phase.
- Accept the increment against its outcome, then retire old dependencies or explicitly fund those that remain.
Does modernization require microservices?
No. A module, adapter or library replacement inside one deployment may remove the relevant constraint. Choose a separate service when its ownership and operating benefit justify distribution, independent deployment and failure handling. The target is a controllable change, not a service count.
Which capability should move first?
Select a capability with a useful outcome, an observable boundary and dependencies the team can resolve. A read-only investigation view can be a good experiment when financial write authority is unclear, but it still needs access, freshness and workload controls. A blocked wallet replacement may first require an inventory and behavior study.
Can both implementations run at the same time?
They can coexist under an explicit contract. Read comparisons and side-effect-disabled shadow work differ from two systems issuing live commands. Define which owner may change each state, how late results are routed and how unfinished work is recovered. Do not send a real financial instruction twice to compare the answers.
How do we know the old component can be removed?
Check all callers, scheduled jobs, provider callbacks, data readers and access to historical records, not just web traffic. Demonstrate that unfinished work has a supported owner and that the replacement meets agreed criteria. Keep required records and operational access; remove temporary machinery only after its dependencies are resolved.
Bring one operating problem, its baseline, known writers and dependencies, and the constraints on releases or provider access. Discuss a bounded assessment with SPINDO.TECH that produces a behavior pack, a replacement boundary, acceptance evidence and a costed transition plan.
Insights
Strangler Migration for iGaming: Transfer Responsibility, Then Retire the Old Path
Replace an operating iGaming capability in stages. Define routing, data authority, ownership of unfinished transactions and different recovery plans before and after new writes.
14 min read
Modular Monolith or Microservices? Choose the Boundary an iGaming Platform Needs
Compare deployment independence, financial consistency, scaling and operating cost. Use a bet-and-wallet example, an extraction plan and four acceptance tests to make an evidence-based architecture decision.
14 min read
Evaluate iGaming Technology Providers Before You Commit to Integration
Compare providers using mandatory gates, observed recovery behaviour and an evidence-based scorecard. Check production scope, support, lifecycle cost and the ability to leave before committing to integration.
14 min read