
- scalability
- peak traffic
- capacity planning
- graceful degradation
Scaling iGaming for Live Events: Protect the Money Path Under Peak Load
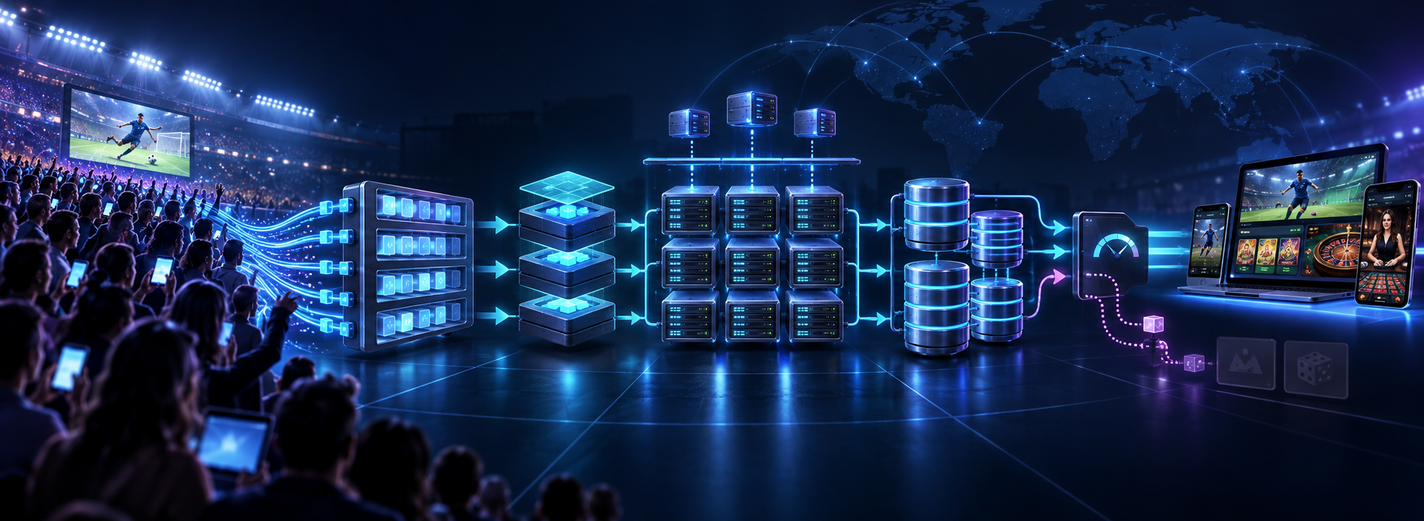
Build a peak-load plan around bet deadlines, durable settlement, dependency limits and measurable recovery. Includes queue and connection-budget examples, test scenarios and an event runbook.
The final whistle can reduce new bet requests while increasing the work that matters most: applying results to accepted tickets and completing wallet movements. A platform that looks healthy during the match can struggle afterwards if settlement shares its database and worker capacity with a burst of reconnecting players or a scheduled promotion.
Peak readiness therefore needs two plans: how much new work the platform can safely admit, and how it will finish work it already owes players. This guide is for platform, engineering and operations teams preparing an iGaming service for live events. The numerical examples are hypothetical planning exercises, not benchmarks or recommended production settings.
Model the event as several workloads, not one traffic number
Use the event timeline to identify different kinds of demand: logins before kick-off, odds updates during play, bet submissions around a decisive moment, reconnects after a network interruption and settlement when results arrive. A promotion can add payment attempts and bonus evaluation at the same time. Their peaks need not coincide, and their costs differ.
For each journey, record its arrival pattern, fan-out to dependencies, state changes, expensive keys, expected completion time and responsible team. A bet request may consume an eligibility check, wallet reservation and supplier call; an odds update may fan out to many connections. Aggregate requests per second conceal that difference.
Google's SRE chapter on overload explains why request counts can be poor proxies for resource cost and discusses customer quotas and throttling. Apply that principle by measuring the constraints of each workload and brand, rather than treating a quiet daily average as event capacity.
Map the relevant modules of the iGaming platform and the operating model of the sportsbook product. Include shared infrastructure: a healthy betting service may still depend on an exhausted authentication pool, a busy wallet database or a supplier quota used by another brand.
Draw the boundary between admission and an accepted obligation
Admission control governs work that has not yet been accepted. A new live bet has a deadline: its market, price and eligibility can change while it waits. Bound the time spent waiting for resources, then evaluate current acceptance conditions at the authoritative decision point. Do not park the request in a long queue and later accept the old displayed offer as though nothing changed.
A refusal before acceptance and an uncertain outcome after submission are different states. If a supplier or wallet committed but the reply was lost, recover the original operation using its stable identity. A timeout does not authorise a new bet or a second money movement. The bet, wallet and settlement architecture explains the records needed to resolve that uncertainty.
Accepted obligations require durable processing. Once a valid result creates settlement work, preserve that work and its relationship to the ticket. Where the integration contract allows it, authenticate and validate an incoming event, durably record it, then acknowledge receipt; apply its financial effect through the wallet owner with duplicate protection. Acknowledgement of receipt is distinct from completed settlement.
Use bounded queues and backpressure to protect resources, but specify what happens at every boundary. If storage is unavailable or full, do not acknowledge an event as durably received; follow the supplier's redelivery and reconciliation contract and raise an incident. Expiring a stale, unaccepted request can be appropriate. Silently dropping a settlement obligation because its queue age is high is not.
Calculate the backlog and the capacity needed to recover
Queue capacity needs a recovery calculation. Consider accepted settlement jobs with uniform processing cost, no initial backlog, no failures or retries, and a fixed sustainable service rate of 400 jobs per second. For 60 seconds, results create 600 jobs per second.
- Growth: 600 minus 400 leaves 200 additional jobs per second.
- Backlog at the end of the burst: 200 multiplied by 60 leaves 12000 jobs unfinished.
- Continuing arrivals: after the burst, assume 200 jobs per second still arrive.
- Recovery capacity: 400 minus 200 leaves 200 jobs per second for the backlog.
- Estimated drain time: 12000 divided by 200 is 60 seconds under these assumptions.
Dividing the backlog by the full service rate ignores continuing arrivals. If arrival rate remains at or above sustainable completion rate, this queue cannot drain without a change. More consumers help only while the constrained dependency can support more completed jobs.
Measure completed work and the age of the oldest unresolved obligation, including failed jobs moved out of the active queue. A shorter queue can hide a growing exception backlog. Account for variation in job cost, redelivery, provider limits, storage headroom and recovery after a worker loss. The arithmetic estimates volume; it does not establish an acceptable player delay or guarantee a deadline. Compare estimated drain time and unresolved age with the agreed journey target before the backlog consumes that allowance; reaching the storage limit is a late warning.
Keep spare capacity appropriate to the measured failure scenario and agreed service targets. Specify whether the event plan must survive loss of a worker group or dependency degradation, and demonstrate that case. A universal spare-capacity percentage cannot replace those assumptions.
Find the limits that adding application replicas cannot remove
Application replicas can increase demand on the database faster than they increase completed transactions. In a separate hypothetical example, 8 replicas with a maximum pool of 40 connections each can request 320 connections. That exceeds an application allocation of 240 connections, before considering any other separately allocated users.
Budget pools across replicas, background workers and operational tools. Keep room for the work needed to diagnose and recover the service. A connection budget is a resource limit, not proof that every allocated connection can perform useful work at once. Inspect query time, lock waits, write throughput, transaction duration and storage behaviour under realistic data volume.
Identify hot keys. Many requests affecting one player wallet, a shared record of exposure from accepted bets or one popular event can serialize on the same authority. Preserve atomic balance checks, unique operation identities and approved acceptance limits. Removing those controls to improve throughput changes correctness. Partitioning independent work, shortening transactions and moving optional reads away from the writer may be better first steps.
Supplier limits also need a shared budget. If each worker independently observes the entire account quota, adding workers can multiply the permitted-looking traffic. Enforce the actual account-wide limit, distribute a bounded allowance and define fair use between brands and workloads. The multi-brand architecture provides the wider isolation context.
Kubernetes documents horizontal autoscaling as a periodic control loop and describes how readiness and startup metrics affect its decisions. For a forecast event, verify usable capacity before the surge: metrics collection, scheduling, image startup, connection establishment and readiness all take time. Count ready replicas doing useful work, not just requested replicas.
Choose scaling signals that reflect the constraint. CPU can be low while workers wait on a locked database or throttled supplier. Combine resource measurements with completed throughput and backlog age; cap concurrency at tested dependency limits. When scaling down, stop taking new jobs, then finish in-flight work or durably hand it off before termination.
Use caching and degradation without changing transaction truth
Caching can remove repeated public reads, but the cached object needs an explicit freshness and access contract. Cache static assets and suitable lobby data close to players. Include the relevant brand, locale and configuration version in shared cache keys. Keep private player data out of a public shared cache; protect any private cache by the actual identity and authorisation boundary.
Displayed odds are an offer view, not acceptance evidence. Track their version and freshness, and revalidate price, market availability, funds and player eligibility where the bet is decided. A stale display must not permit a transaction that the authoritative services would reject. If essential checks cannot be completed, restrict the affected action rather than bypassing the checks.
Test a cold cache as well as a warm one. Simultaneous expiry, a deployment or loss of a cache tier can send a burst to the origin. Bound refresh concurrency, spread suitable refresh timing and warm only the working set the event needs. Warming every key can itself overload the system.
Agree degradation priorities before the event. Pause expensive optional recommendations, report exports and campaign jobs when they threaten critical resources. Reserve processing for already accepted financial work and the controls required to serve players safely. A cached public view may remain useful if its freshness is honestly represented; a stale balance must not become authority for spending.
AWS's guidance on timeouts, retries, backoff and jitter warns that retries can amplify overload and that a timeout does not prove an operation had no effect. Give retries one explicit owner at each integration boundary, a finite budget and suitable backoff with jitter. Retry side-effecting work only under the integration's verified idempotency rules; investigate an unknown original outcome before creating a new operation.
Separate original demand from retry traffic. When a dependency is recovering, pace replay and new calls within the same tested budget. Restarting all workers, warming all caches and releasing every deferred job together can create another peak before players see recovery.
Test the traffic you will receive and the failures it will cause
A fixed number of simulated users can understate an externally driven peak. When each virtual user waits for a slow response before continuing, incoming work can fall exactly when the platform is struggling. Grafana k6 explains this difference between closed and open workload models and the problem of coordinated omission. Use an arrival-driven model where it matches real independent arrivals; retain session-based models for journeys whose pacing actually depends on responses.
Record the demand the generator really delivered, not just its configured target. Confirm it has enough resources and sessions to sustain the intended arrival pattern. Report offered, admitted, rejected and completed work separately, with completion latency and unfinished obligations. Define targets per journey and brand before the run; an average across public page reads and wallet writes is not a useful acceptance criterion.
- Event shape: test a sudden step, a short intense burst and sustained load, including odds fan-out and the post-result settlement wave.
- Data shape: use realistic account and ticket volumes, concurrent access to hot keys, one noisy brand and both cold and warm caches.
- Dependency failure: introduce supplier delays, quota exhaustion and a lost response after a committed operation; verify outcome recovery without duplicate effects.
- Worker failure: interrupt processing, redeliver events and restart consumers; verify that obligations survive and effects remain unique.
- Recovery: reduce the offered load but keep realistic continuing arrivals. Measure backlog drain, old exceptions and the effect of gradually restoring optional features.
Run disruptive tests in an isolated, representative environment using permitted test integrations and data. Compare ticket obligations with wallet records and supplier evidence after the run. A fast endpoint, an empty queue or an absence of server errors alone cannot prove the correct money result. These are recommended verification scenarios, not claims that this platform has passed them.
Run the event with explicit controls and a recovery owner
Before the event, the engineering owner should confirm ready capacity, database budgets, supplier allowances, storage headroom and the tested failure envelope. Operations should know who can adjust admission, pause optional work, investigate uncertain outcomes and contact the supplier. Changes need explicit scope, access and an audit record.
Use a runbook with observable triggers and reversible actions. If obligation age grows while completion throughput stalls, first identify the constrained boundary. Pause competing optional work and limit new admission where appropriate; increase workers only within demonstrated downstream capacity. If an authoritative money or eligibility service is unavailable, stop affected new transactions safely and preserve uncertain work for recovery.
Keep players informed about the state of their own operation: pending, rejected or completed, based on recorded evidence. Support needs a safe lookup by operation or ticket identity, not an instruction to ask everyone to submit again. Do not expose internal provider diagnostics or other players' data in the status response.
The recovery owner should pace backlog processing, resolve failed jobs and reconcile accepted obligations with posted money movements. Restore optional work gradually while watching completion throughput and unresolved age. End the incident only when the relevant financial and operational checks are satisfied, not when inbound traffic falls. Monitoring unfinished player journeys helps make those checks visible.
Afterwards, compare forecast and observed workload, ready capacity, bottlenecks, degradation decisions and recovery time. Turn differences into specific changes with owners and evidence required for the next event. Peak readiness becomes repeatable when the team can explain both the refusal of new work and the completion of accepted obligations.
For the organisational side of the plan, use the product-team integration guide to clarify responsibility and operating context. If the capacity work also changes storage or write ownership, the live-platform migration guide addresses the obligations and reconciliation that must survive the move.
- Workload sheet: event timeline, journey and brand mix, fan-out, deadlines, arrival assumptions and the source of each estimate.
- Capacity sheet: measured sustainable completion rates, database and supplier budgets, ready-capacity lead time, queue storage and drain calculations with continuing arrivals.
- Degradation plan: protected financial and eligibility work, optional features to pause, admission rules, approved controls, player messages and recovery ownership.
- Evidence pack: delivered test load, tail latency, unresolved obligation age, failure and replay results, reconciliation evidence and the actions required before the next event.
Should every peak be handled by adding replicas?
Add replicas when more independent application work can use available downstream capacity. If lock contention, database throughput or a supplier quota limits completion, extra replicas can increase waiting and retries. Identify the constraint and keep total concurrency within the tested budget.
Can settlement jobs expire when a queue is overloaded?
Queue age can trigger an incident or controlled recovery, but it does not cancel an accepted obligation. Preserve the durable record, account for failed jobs and resolve financial effects through the authorised owner. A stale unaccepted live-bet request has a different policy: it can be rejected before acceptance.
How much spare capacity is enough?
There is no useful universal percentage. Choose the workload forecast, service targets and failure scenario first. Measure sustainable completion under those conditions, include startup delay and continuing arrivals, then demonstrate that the plan can serve protected work and recover within the agreed targets.
When can the team declare recovery complete?
Use agreed evidence for the affected journeys: durable obligations accounted for, financial effects reconciled, uncertain outcomes and failed jobs resolved or owned with an approved plan, and completion and delay targets restored. Lower traffic or healthy CPU alone does not establish recovery.
Bring the event timeline, current journey metrics, queue history and database and supplier limits. SPINDO.TECH can help define the capacity questions, degradation controls and verification work needed before opening more traffic.
Insights
Observability for iGaming Platforms: Detect and Investigate Partial Failures
Build monitoring around player outcomes, durable payment and bet records, useful traces and actionable alerts. Learn to detect stalled journeys even when APIs appear healthy.
14 min read
Integrating an iGaming Product Team: From Access to Accountable Delivery
Give a new product team the context, decision paths and controlled access to deliver safely. Use a bounded first change, an evidence-led onboarding plan and a practical continuity check.
14 min read
Planning Data Migration for a Live iGaming Platform
Plan a live iGaming data migration around balances, open operations and player restrictions. Define mappings, capture changes, reconcile at a common boundary and rehearse cutover and recovery.
14 min read